コース進捗 コース目次 48レッスン中 48件を公開中
第0部 読み方ガイド:私たちは何を学ぶのか
第1部 世界モデル:エージェントの頭の中にある実験場
第2部 画面を状態に変える:LeWMのモデル構造
第3部 モデルの抜け道を防ぐ:予測損失とSIGReg
第4部 モデルを行動に使う:潜在空間での計画
第5部 エンジニアリング再現:論文から動くシステムへ
第6部 LeWMは何を学んだのか
第7部 「予測が正確」でも「計画がうまくいかない」のはなぜか
第8部 再現者から研究者へ
付録 数学・実装・再現・査読のための参照資料
まず大きな絵
- appearance を変えるphysical transition は固定。
- physics を変えるappearance はほぼ固定。
- action を変えるfull history は固定。
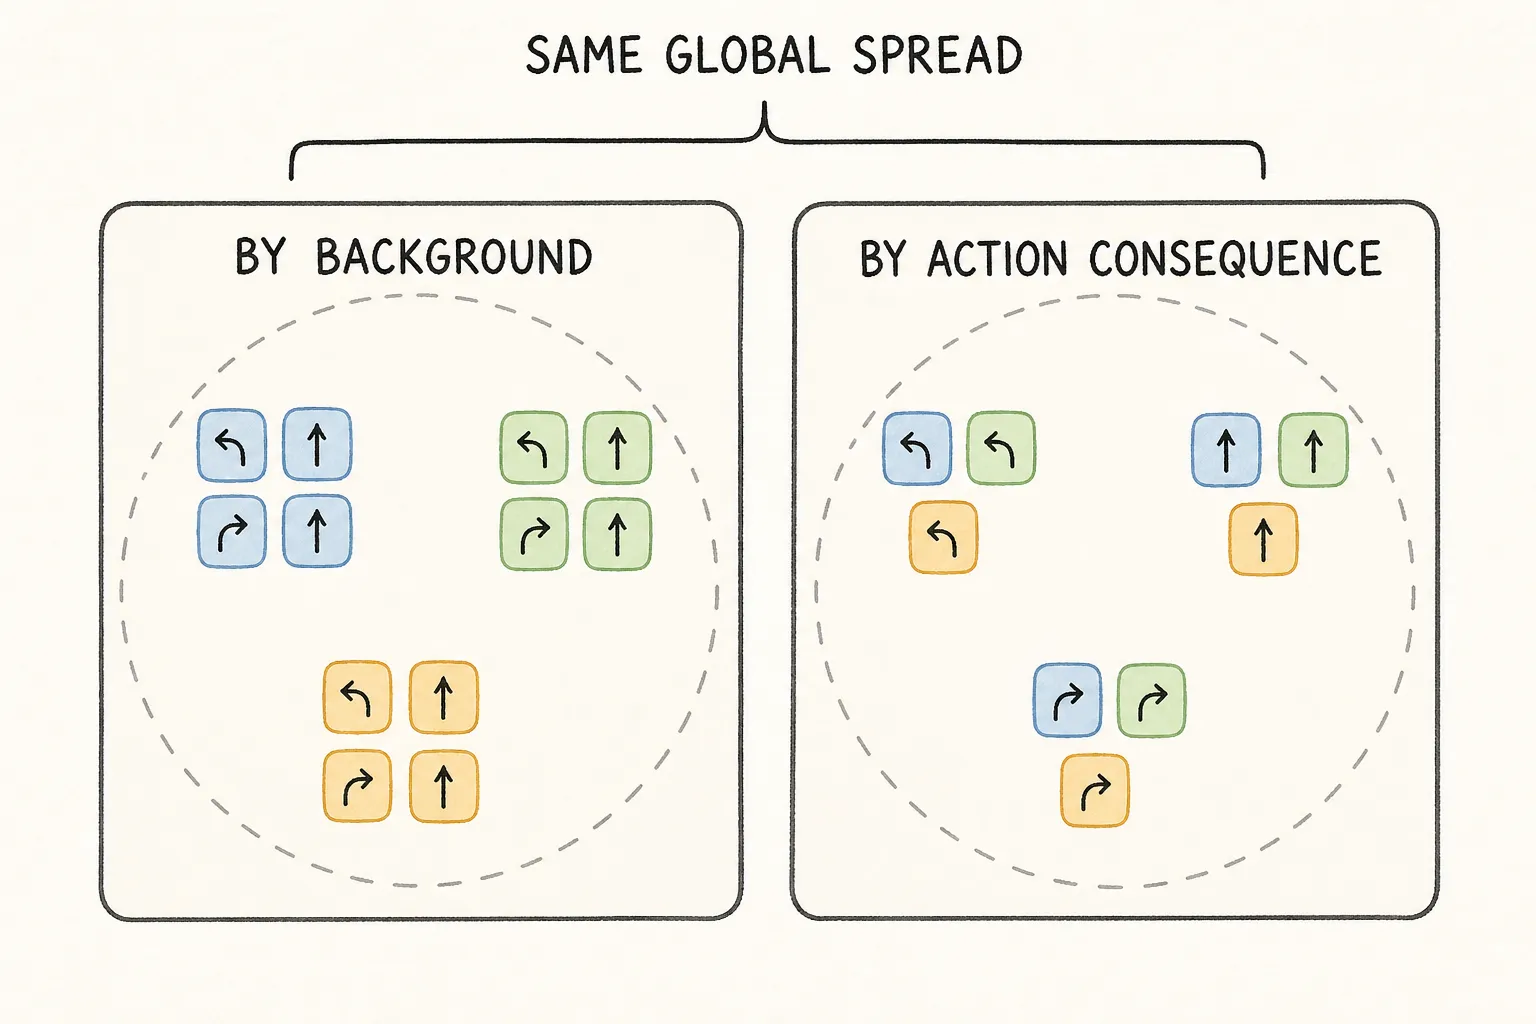
小さなお話
passport office が全員に違う card を作ります。archive は collapse しません。しかし card には shirt color と wallpaper だけがあり、motion direction や通れる gate がありません。
latent も同じです。background texture が多くの dimension を満たし、小さな velocity/contact variable が消えます。global variance、rank、pretty projection は一部 failure を除きますが、task-relevant dynamics の保存を証明しません。
本当のルール
matched intervention を使います。
- simulator state/transition を固定し、environment が dynamically irrelevant と保証する appearance factor だけ変更。
- appearance をほぼ固定し、next outcome を変えると分かっている physical variable だけ変更。
- complete observable history を固定し、proposed action だけ変更。simulator を reset し、各 predicted branch と matching real transition を比較。
appearance は自動的に nuisance ではありません。traffic-light color、shadow、texture は real control state を示す場合があります。intuition ではなく experiment が invariance を保証します。
observation sufficiency が先です。identical render の opposite velocities は1 frame から読めません。representation failure と言う前に、motion が observable になるだけの history を与えます。history に clue があるのに latent/predicted future が collide すれば、より強い test です。
action sensitivity には3段階あります。output が変わるか、正しい方向へ変わるか、state–action interaction に依存するか。shuffled、zero、opposing、withheld actions は役立ちますが OOD pair も作れます。nonzero response だけで correct dynamics ではありません。
だまされる反例
同じ PushT pose を3つの harmless floor texture で描きます。次に、appearance はほぼ同じで opposite motion/different contact の view を作ります。harmless texture の方が prediction を大きく変えるなら、この controlled environment では wrong distinction を優先しています。
PhyLatent は3つの operational failure を名付けます。
- physical invariance collapse: appearance-only movement が selected physical transition を上回る。
- physical identifiability collapse: selected physical variables で遠い states が latent で近い。
- counterfactual dynamics collapse: materially different action consequences が圧縮される。
1 paper 内の定義で、universal taxonomy や theorem-level identification ではありません。threshold、simulator variable、scale、observability、pair selection が必要です。PhyLatent の baseline description は stopped future target を使い、original connected-target LeWM v3 と違います。提案 training も privileged physical targets を使います。
実験のレシート
later LeWM-family proposals は違う supervision を買います。
- PSG-JEPA:LeWM forward loss/SIGReg に training-only proprioceptive-state head と multi-horizon joint-angle change (q_{t+k}-q_t) head。privileged labels は test にない。
- SCALE:(1-\mathrm{corr}(d_z,d_q)) を加え、squared latent pair distance と standardized selected simulator-state distance を align。同じ labels の regression control は pairwise geometry を形づくらない。authors report 15/15 task–solver averages 改善。各 training config は1 seed、evaluation sets は episode sampling。
- AC-MTM:SIGReg を除き、connected forward MSE + training-only Action-NCE inverse head。in-batch actions から recorded continuous-action block を識別。target network、stop-gradient、pretrained encoder、reconstruction loss なし。inverse head は test で破棄。matched 3-training-seed study は4 standard tasks average で SIGReg と同等、PushT で下回り、OGBench Visual Scene trajectory-goal stress test は80% vs 58%。random 52% は1回の50-episode run。
PSG-JEPA/SCALE は privileged simulator labels、AC-MTM は informative action variation/observable consequence を必要とします。どれも original v3 ingredient ではなく、本レビューで independent reproduction はありません。
各 diagnostic で simulator reset state、history、intervention、real outcomes、appearance control、support、checkpoint、threshold、seeds を保存します。representation improvement を fixed-planner ranking/success と交差させます。よい probe を cost が読まない場合があります。
3つのクイック質問
- globally non-collapsed representation が control variable を失うのはなぜですか。
- appearance change を irrelevant と呼ぶ前に何が必要ですか。
- action branch を matching real outcome と比べるのはなぜですか。