コース進捗 コース目次 48レッスン中 48件を公開中
第0部 読み方ガイド:私たちは何を学ぶのか
第1部 世界モデル:エージェントの頭の中にある実験場
第2部 画面を状態に変える:LeWMのモデル構造
第3部 モデルの抜け道を防ぐ:予測損失とSIGReg
第4部 モデルを行動に使う:潜在空間での計画
第5部 エンジニアリング再現:論文から動くシステムへ
第6部 LeWMは何を学んだのか
第7部 「予測が正確」でも「計画がうまくいかない」のはなぜか
第8部 再現者から研究者へ
付録 数学・実装・再現・査読のための参照資料
まず大きな絵
- 質問を一つfailure と prediction を名指します。
- 小さな test を一つsandbox で mechanism を一つ変えます。
- 負け方を一つscore より先に falsifier を書きます。
小さなお話:十二隻の船
港に十二隻の船があります。planning geometry、uncertainty、representation structure、search/transfer を試す船です。どれも「優勝者」ではありません。それぞれが小さな出航カード、つまり question、一つの変更、measurement、港へ戻る condition を持ちます。
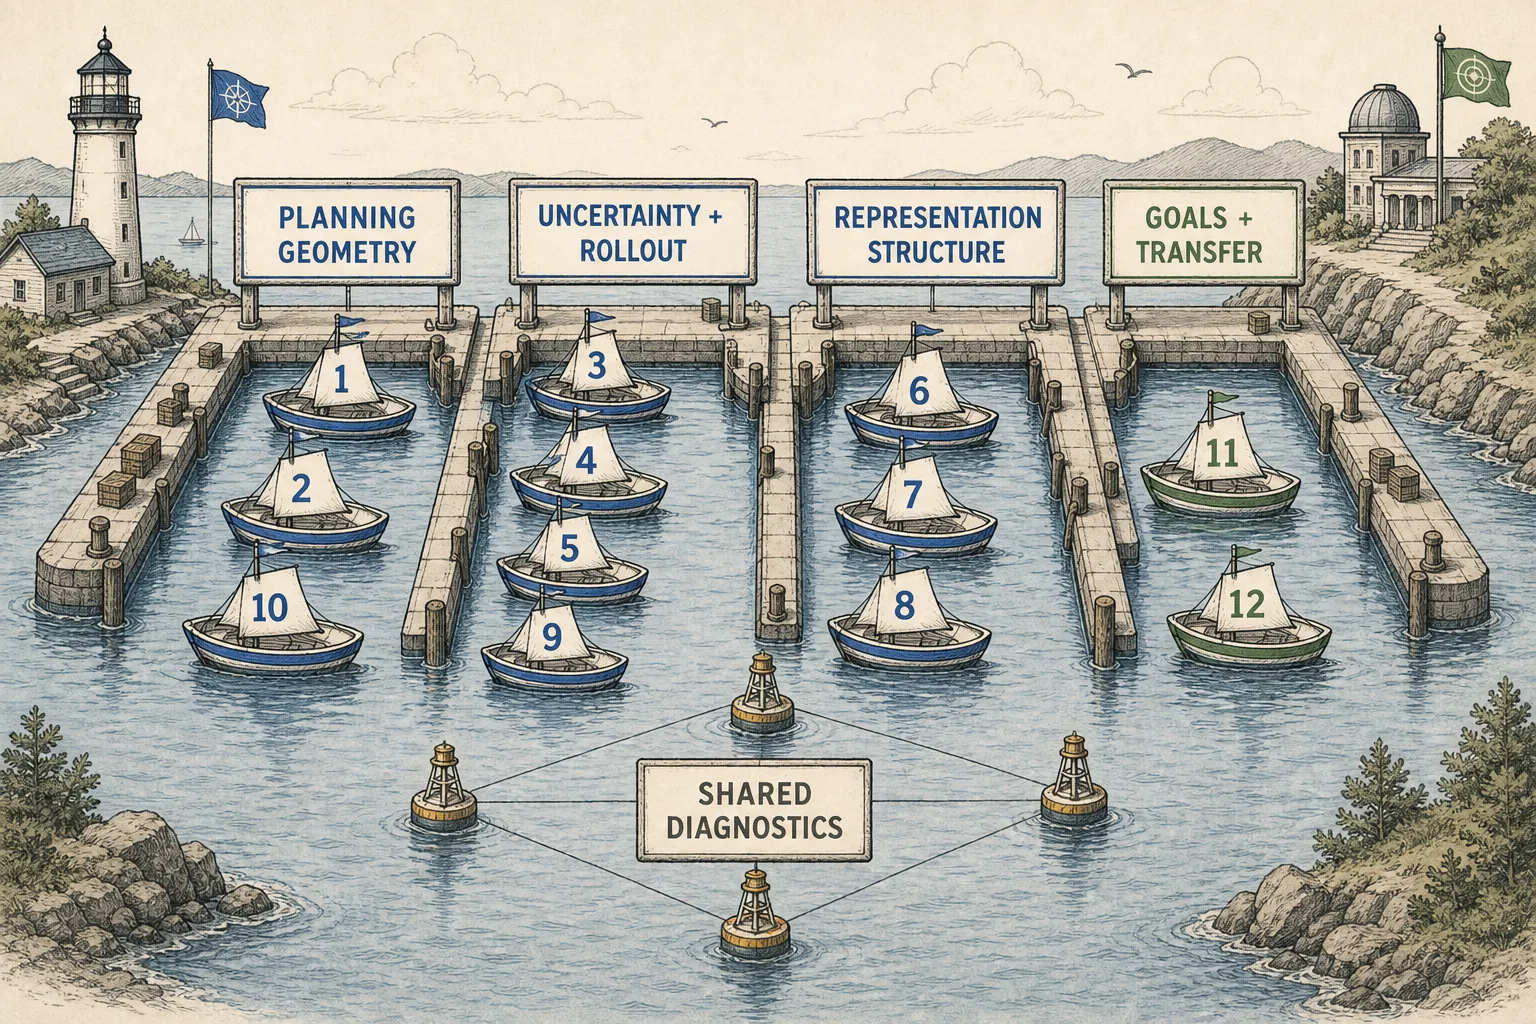
これは experiment plan で、新しい result ではありません。同じ berth は difficulty、promise、evidence が同じという意味ではありません。
技術のリュック:十二枚の出航カード
全 card は frozen LeWM baseline、episode-disjoint data、宣言した seed、matched training/planning budget、raw log、positive/null/negative reporting から始めます。simulator state、shortest path、reward、depth、language annotation が component の training/evaluation に入るときは privileged と明記します。
| # | Project | 変更と測定 | idea を弱める結果 |
|---|---|---|---|
| 1 | Latent distance vs true shortest path | TwoRoom で latent pair distance と oracle geodesic distance を相関。same-room/across-wall、near/far に層別化 | held-out layout で相関が消える、または相関改善が candidate ranking を改善しない |
| 2 | Directed reachability | trajectory offset と constructed negative から budget-conditioned ordered score を学び、withheld direction/horizon を test | score が symmetric、dataset frequency 追随、または matched oracle-budget ranking に失敗 |
| 3 | Predictive uncertainty calibration | spread/error bin を予測し、confidence と後の self-fed rollout error を比較 | confidence が鋭いが uncalibrated、または horizon length だけを追う |
| 4 | Ensemble epistemic uncertainty | matched-seed / bootstrap model を学習し、support 内外の disagreement を比較 | member が同じ unsupported shortcut に誤って同意、または disagreement が optimization noise だけを表す |
| 5 | Multi-step training | inference と budget を固定し、宣言した rollout-consistency / multi-horizon loss を一つ追加 | one-step loss は改善するが long rollout/planning は悪化、または extra update 由来の gain |
| 6 | Temporally hierarchical latents | coarse state / action chunk を学び、reconstruction、reuse、support、two-level cost を監査 | high-level error、unsupported subgoal、overhead が節約 low-level compute を上回る |
| 7 | Local Gaussian structure, global topology | local neighborhood / subspace を regularize し、global spread と doorway continuity を別測定 | anti-collapse が弱まる、または extra capacity なしでは topology gain が消える |
| 8 | Action-controllable subspace | action-sensitive change と content を分け、intervention、nuisance change、弱く controlled な variable を test | “control” space が background/task ID を encode、または遅い task-critical state を捨てる |
| 9 | Counterfactual-dynamics probes | matched state で recorded/withheld action の prediction を simulator transition と比較 | branch separation はあるが consequence が誤る、または recorded action だけ正確 |
| 10 | Support-constrained CEM | support distance を penalty にするか empirical action/macro-action anchor 近くを探索し、constraint strength を報告 | strict gate が valid novel detour を塞ぎ、loose gate は model exploit を許す |
| 11 | Goal images to language goals | 宣言した language-to-goal interface を追加。object–relation combination を hold out し、oracle goal encoding と比較 | success が composition でなく memorized phrase / paired-goal leakage に依存 |
| 12 | Cross-environment latent alignment | paired anchor で environment 間を align し、held-out dynamics、view、task を test | alignment は probe を改善するが、どちらかの world の transition prediction/planning を悪化 |
Project 1–2 は distance と directed budgeted feasibility、3–4 は predictive spread、ensemble disagreement、support distance、actual error、5–6 は長い training target と hierarchy、7–9 は action に必要な representation structure、10–12 は search、goal、transfer を分けます。各 card が自分の test に勝つ前に結合すると、診断を壊します。
壊してみる
Support-constrained CEM はよい自己攻撃です。一つの TwoRoom layout で、unconstrained optimizer は不可能な shortcut を取ります。中程度の support rule は doorway へ導きます。次に training trajectory にない valid novel detour を入れます。厳しすぎる rule は唯一の成功 path を塞ぎます。
support penalty を sweep し、両 failure family を見せます。oracle feasible-route label は evaluation だけに使います。best threshold が goal type で変わるなら、interaction を報告し、一平均に隠しません。universal threshold がなくても project は科学的に成功できます。model exploitation と over-conservative search の trade-off を地図化したからです。
全 card に removal test が要ります。geometry では wall を除き、controllability では action coverage を均し、uncertainty では controlled out-of-support sample を注入し、grounding では privileged label を shuffle し、alignment では paired anchor を除き、composition では language combination を hold out します。easy condition だけを生き残る result は広い claim を得ません。
実験レシートと証拠の境界
- これらは tutorial-generated hypothesis で、報告済み improvement ではありません。直接の inspiration は LeWorldModel v3、RC-aux、TRM、Sub-JEPA、SMWM、VLWM、Temporal-Distance JEPA、Fast-LeWM、Hi-LeWM、PSG-JEPA です。
- 後の diagnostic/decision route は TwoRoom reproduction、VIScore、ACPC、Objective Bottleneck、Traj-LeWM、SCALE、AC-MTM、DA-LeWM です。明確に限定した TwoRoom 再実装以外の evaluation は author-reported です。
- LeWM、RC-aux、Temporal-Distance JEPA、Sub-JEPA、Fast-LeWM、Hi-LeWM、stable-worldmodel、passive-identifiability、SMWM、PSG-JEPA、tinylab、VIScore、ACPC、Traj-LeWM、AC-MTM では凍結 public implementation を確認しました。cutoff までに TRM、VLWM、SCALE、DA-LeWM、PhyLatent、TC-LeWM、QQWorld、ProWorld、controlled-identifiability、2024 “HWM” 教材略称 route では未確認です。public code は independent reproduction ではありません。
- source version は 2024-06-01 から DA-LeWM v1 の 2026-08-19 まで、evidence cutoff は 2026-08-20、Asia/Tokyo。許される動詞は “test”“hypothesis”“falsifier”“この locked setting で支持” です。“改善するはず”“uncertainty を解決”“privileged label で学習して pixels-only”“compositional understanding を証明” は避けます。
3つのクイック質問
- research idea を executable launch card にする五つの field は何ですか?
- ensemble disagreement と actual rollout error が別 instrument なのはなぜですか?
- support constraint は同じ planner をどう助け、どう害せますか?