Course progress Course outline 48 of 48 lessons available
Part 0 — Reading Guide: What Exactly Are We Going to Learn?
Part 1 — World Models: An Internal Sandbox for the Agent
Part 2 — Turning Images into State: The LeWM Architecture
- 06 Chapter 5 — Trajectory Data: To the Model, the World Is Not an Image Collection available now
- 07 Chapter 6 — The Visual Encoder: Issuing a “State Passport” for Every Frame available now
- 08 Chapter 7 — The Dynamics Predictor: Moving Time Forward in the Mind available now
- 09 Chapter 8 — A Complete Forward Pass: Follow One Batch from Start to Finish available now
Part 3 — Preventing the Model from Cheating: Prediction Loss and SIGReg
- 10 Chapter 9 — The Most Dangerous Shortcut: Representation Collapse available now
- 11 Chapter 10 — Prediction Loss: How the Model Learns the Next Step available now
- 12 Chapter 11 — The Intuition Behind SIGReg: Letting Representation Space “Breathe” available now
- 13 Chapter 12 — Keep the Mathematics Minimal but Sufficient available now
- 14 Chapter 13 — The Original LeWM’s End-to-End Training Mechanism available now
- 15 Chapter 14 — Train a Model That Does Not Collapse Immediately available now
Part 4 — Putting the Model into Action: Planning in Latent Space
- 16 Chapter 15 — Goal-Conditioned Planning: From “Where Am I?” to “Where Do I Want to Go?” available now
- 17 Chapter 16 — Latent Euclidean Distance: Convenient, but Not Necessarily Reliable available now
- 18 Chapter 17 — CEM: Searching for Actions Through an Elimination Tournament available now
- 19 Chapter 18 — MPC: Do Not Trust the Model for Too Long at Once available now
- 20 Chapter 19 — Long-Horizon Rollouts: How Small Errors Snowball into Major Failures available now
- 21 Chapter 20 — Implement a Minimal LeWM Planner from Scratch available now
Part 5 — Engineering Reproduction: From Paper to Running System
- 22 Chapter 21 — The Official Repository and Experimental Environment available now
- 23 Chapter 22 — First Experiment: A TwoRoom Smoke Test available now
- 24 Chapter 23 — Second Experiment: Reproducing PushT available now
- 25 Chapter 24 — How to Evaluate a World Model Fairly available now
- 26 Chapter 25 — Failure-Diagnosis Manual available now
Part 6 — What Has LeWM Actually Learned?
- 27 Chapter 26 — Linear Probes: Which Physical Variables Are Encoded in the Latent State? available now
- 28 Chapter 27 — Give Latent Space a “Health Check” available now
- 29 Chapter 28 — Violation of Expectation: Is the Model Surprised by “Impossible Events”? available now
- 30 Chapter 29 — How to Discuss “Understanding the World” Rigorously available now
Part 7 — Why “Accurate Prediction” Can Still Produce “Poor Planning”
- 31 Chapter 30 — The Gap Between the Training Objective and the Planning Objective available now
- 32 Chapter 31 — Global Non-Collapse Does Not Guarantee Preservation of Task-Relevant Dynamics available now
- 33 Chapter 32 — When Is an Isotropic Gaussian Prior Too Strong? available now
- 34 Chapter 33 — Long-Horizon Planning: Predict Farther or Plan More Intelligently? available now
- 35 Chapter 34 — From Positional Distance to Task Progress available now
- 36 Chapter 35 — Multi-Task Learning, Real Robots, and Visual Distractions available now
- 37 Chapter 36 — Theoretical Boundaries: When Can the True State Be Identified? available now
Part 8 — From Reproducer to Researcher
Appendices
- 41 Appendix A — The Minimum Necessary Mathematical Toolkit available now
- 42 Appendix B — PyTorch Implementation Quick Reference available now
- 43 Appendix C — Complete Tensor-Shape Table available now
- 44 Appendix D — Experiment Configuration Cards Current lesson
- 45 Appendix E — Paper Timeline and Evidence Levels available now
- 46 Appendix F — Glossary available now
- 47 Appendix G — Reproduction Checklist available now
- 48 Appendix H — Expert-Review Checklist available now
The big picture
- Name the worldtask, data, revision
- Name the clockticks, steps, horizon
- Name the budgettrain, search, evaluate
- Stamp the sourcepaper ≠ code ≠ run
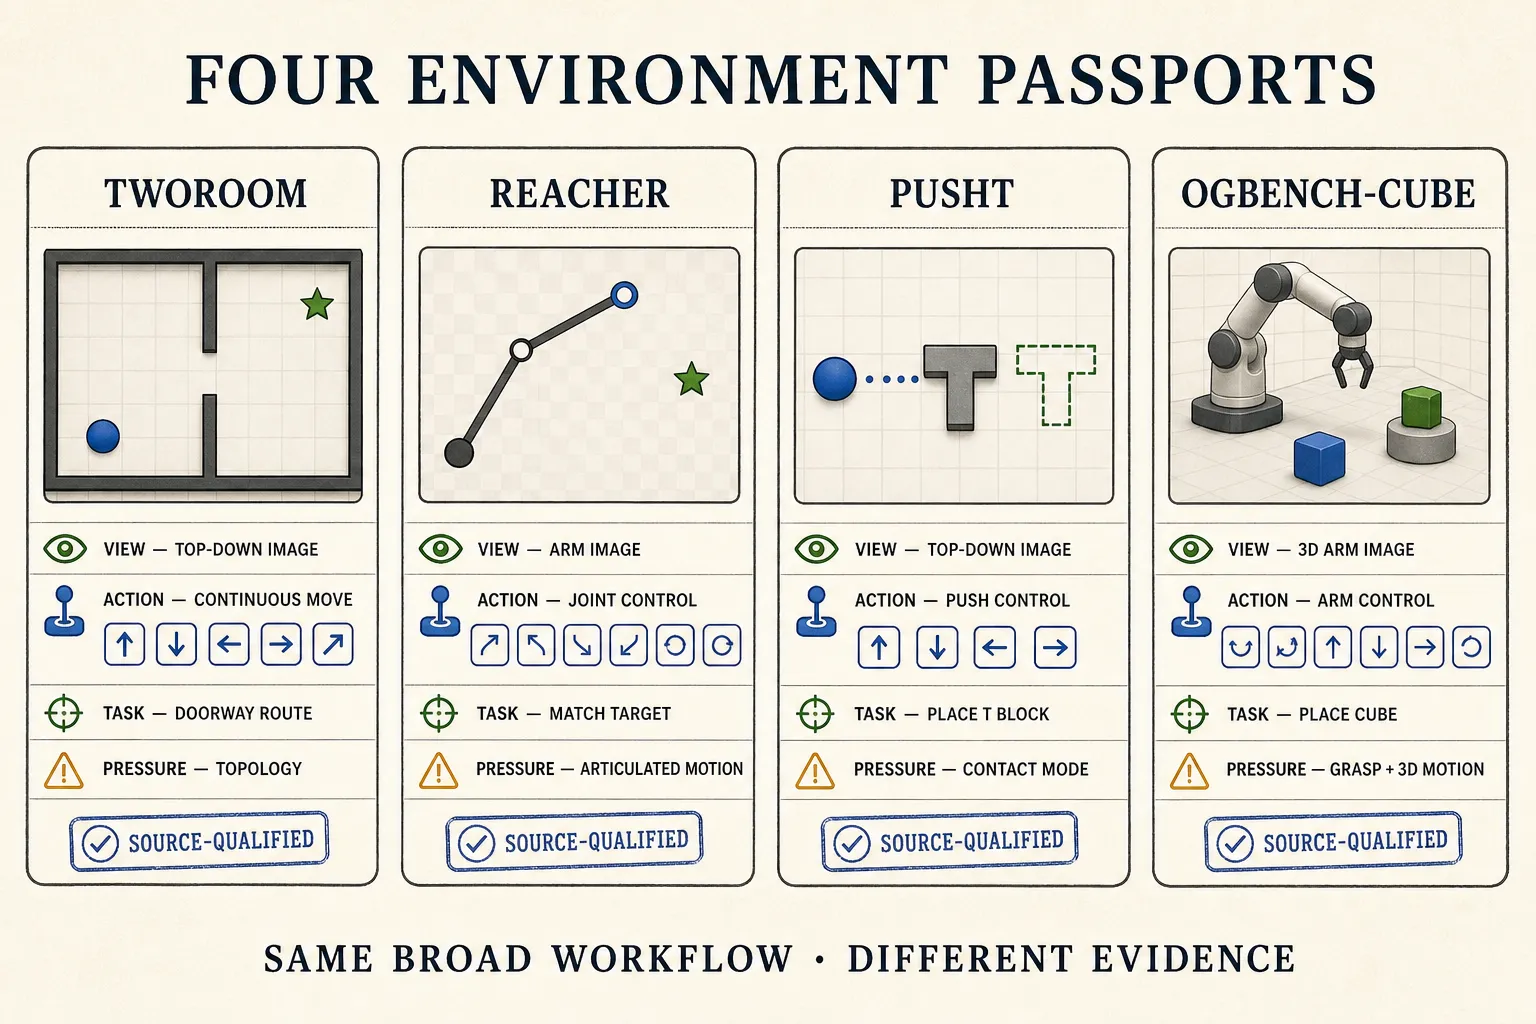
A tiny story
Four teams say, “We tested a world model.” One crossed a doorway, one moved a two-joint arm, one pushed a T, and one picked up a cube. The sentence is true but too small to compare.
A configuration passport records the world, artifact, observations, action grouping, history, training, planning, execution, goal, metric, seeds, and compute. If a field cannot be verified, write not verified. A blank invites investigation; a guessed value manufactures evidence.
The configuration backpack
Four benchmark passports
| World | Paper card | Frozen-code card | Pressure and boundary |
|---|---|---|---|
| TwoRoom | 10,000 episodes; average 92 environment steps; noisy door-then-goal heuristic; 10 epochs; history 1; non-PushT CEM at most 10 refinements | tworoom.h5; pixels/actions/proprioception; frame skip 5; global history 3, max 100 epochs; evaluation 50 episodes, goal offset 25, action budget 50, horizon 5, executed prefix 5; shared CEM 30 refinements | Doorway topology exposes straight-line latent shortcuts. A simple 2-D sandbox does not represent all world modeling. |
| Reacher | 10,000 episodes × 200 steps; Soft Actor-Critic collection; 10 epochs; paper history not explicitly verified in the cited statement | reacher.h5; pixels/actions/observation; frame skip 5; global history 3; swm/ReacherDMControl-v0, qpos_match; evaluation 50, offset 25, budget 50, horizon/prefix 5/5 | Simulated articulated control, not general robotics evidence. Success tolerance and full environment behavior require the resolved platform revision. |
| PushT | 20,000 expert episodes; average 196 steps; 10 epochs; history 3; 300 candidates, 30 elites, initial variance 1, horizon 5, at most 30 CEM refinements | global history 3, max 100 epochs, SIGReg weight 0.09; YAML names pusht_expert_train.lance; inspected public artifact/README use compressed HDF5; evaluation offset 25, budget 50, horizon/prefix 5/5, frame skip 5 | Contact location, orientation, and push-without-pull history matter. Scores do not transfer to a real robot. |
| OGBench-Cube | 10,000 episodes × 200 steps; benchmark heuristic; 10 epochs; history 3; non-PushT CEM at most 10 refinements | ogbench/cube_single_expert.h5; pixels/actions/observations; frame skip 5; swm/OGBCube-v0, single cube, 224-pixel rendering; evaluation 50, offset 25, budget 50, horizon/prefix 5/5; shared CEM 30 | 3-D motion and grasping differ from “PushT in 3-D.” Privileged fields set the environment goal; they are not evidence that original LeWM training receives privileged state. Success tolerance remains revision-bound. |
One model step groups five environment actions in these frozen cards. A five-step horizon therefore spans 25 environment actions. The same cards execute all five model steps before replanning. That is one MPC timing choice, not a universal LeWM constant.
TwoRoom also has a version-history trap. An independent reproduction audited paper-side offset 100 and budget 150 against repository 25/50. Those 100/150 values belong to LeWM v1/v2 history; current v3 Appendix F.1 states 25/50. The reproduction further reports, for its TwoRoom reimplementation only: gather every action in each frame-skip block, derive action-encoder input width programmatically, use ImageNet pixel normalization, and z-score actions. Do not promote those audit findings into universal benchmark rules.
Never average paper and code
| Field | Paper v3 label | Frozen-code label |
|---|---|---|
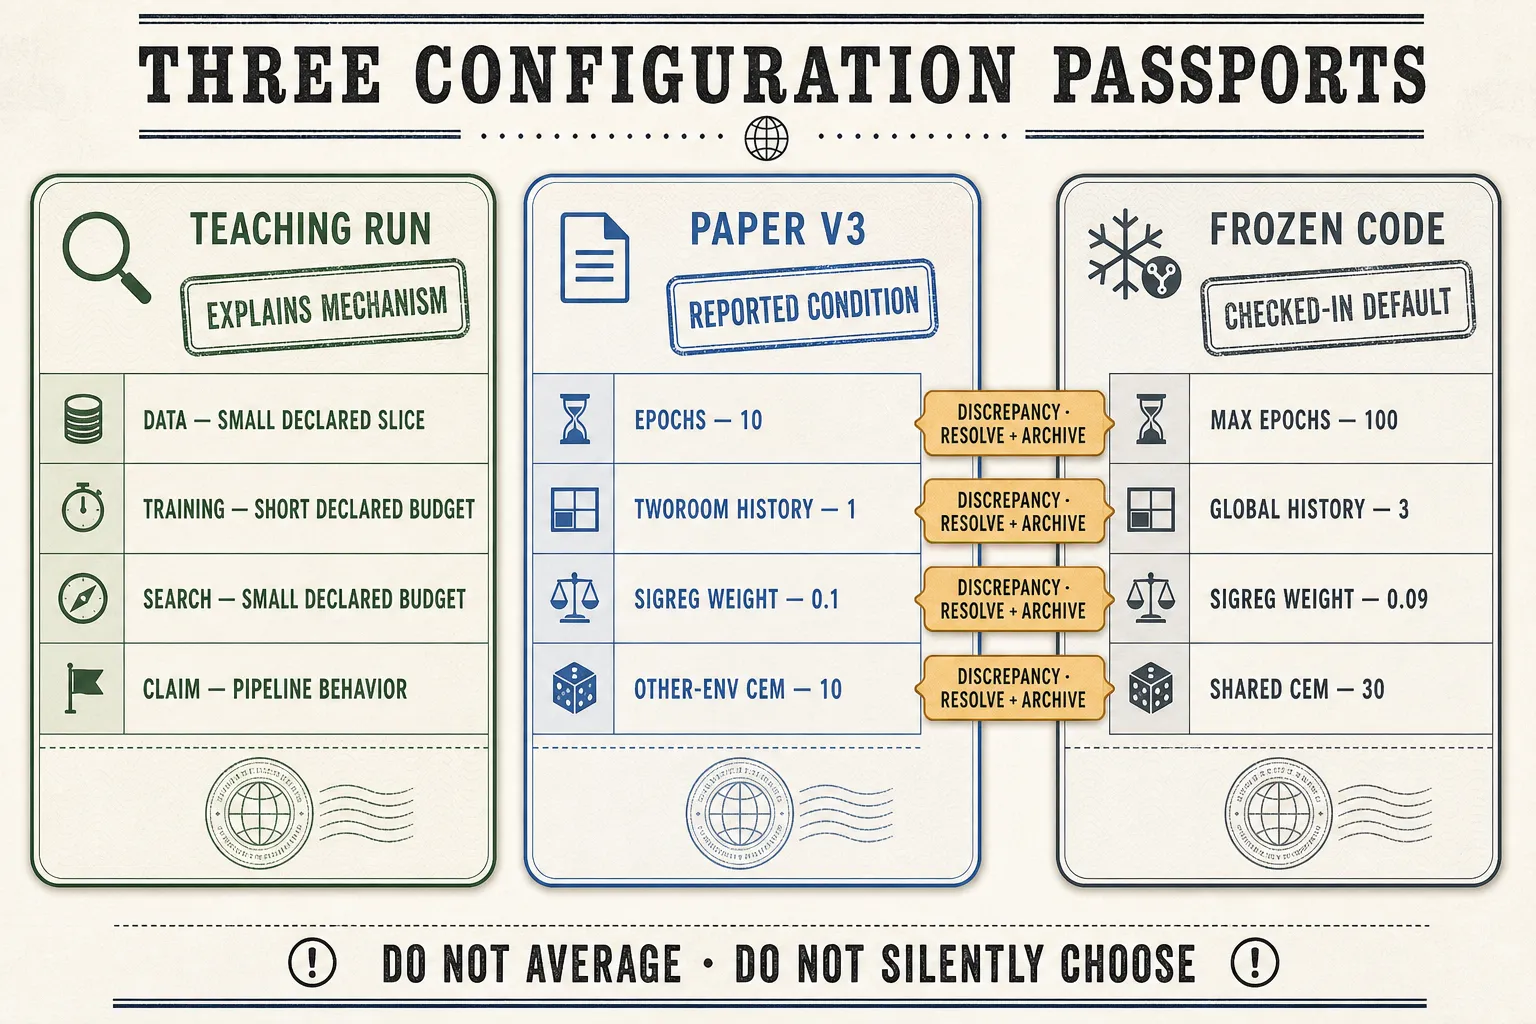
| training duration | 10 epochs for four named tasks | global maximum 100 |
| TwoRoom history | 1 | global default 3; no data override |
| SIGReg trade-off | default 0.1 unless specified | 0.09 |
| non-PushT CEM refinements | at most 10 | shared solver 30 |
| PushT data name/format | trajectory description following DINO-WM | Lance filename; inspected public artifact compressed HDF5 |
Neither column “wins.” The paper describes the reported condition; the frozen repository describes what that revision resolves without extra overrides. A real run adds a third label: resolved run, with every inherited value printed and archived. Original LeWM v3’s method card also says one shared trainable encoder, connected targets, no stop-gradient, EMA teacher, or pretraining; changing that belongs on the run passport.
Three useful run cards
A teaching run is a cheap, transparent mechanism check. Use an episode-disjoint slice that still contains door crossings or varied contacts; shorten capacity or budget if needed; retain action-swap, latent-spread, one-step, self-fed rollout, CEM-trace, and execution diagnostics. Label every changed field TEACHING, never PAPER.
choose one teaching purpose
freeze data slice, episode IDs, revisions, and seed
resolve every inherited value
run data -> forward -> rollout -> search -> execution gates
archive the resolved card with logs and outputs
A paper reproduction locks the cited task, data, history, training, model, planner, baselines, seeds, and evaluation, then records every discrepancy. Keep three levels distinct: (1) load a pinned artifact and obtain finite outputs, (2) evaluate it on locked episodes and planner budget, (3) retrain across declared seeds and compare the stated statistic. Passing level one does not imply level three. Hydra can compose today’s config; it cannot recover an unarchived historical override, dependency, GPU stack, or conversion.
A single-GPU adaptation first records GPU/memory, software, precision, wall-clock, storage, and latency. Separate training budget, model-evaluation budget, and planning budget. Smaller batch can change SIGReg’s batch statistic; fewer projections change its approximation; shorter history changes information; fewer CEM candidates/refinements change search; shorter horizon changes the control problem. These savings are not equivalent, and a changed card cannot inherit a paper score.
The trick that fools us
Run A uses a pretrained encoder, 300 candidates, 30 refinements, five seeds, and same-trajectory goals. Run B trains end to end, uses 64 candidates and 5 refinements, one seed, and broader-split goals. Both report 80%. These are deliberately hypothetical cards, not descriptions of original LeWM v3.
Lock artifact, episode IDs, preprocessing, goal rule, success definition, time abstraction, model, training compute, action/search budget, seeds, and statistic; vary one named factor. Equal scores still do not prove equal mechanisms—inspect rollout, cost ranking, and failure distribution.
Evidence receipt
LeWorldModel v3, especially Appendices D–F, and frozen official code 8edfeb336732b5f3ce7b8b210d0ba370a09e2cac support the paper/code cards. TwoRoom independent reproduction v1 and its tinylab artifact support only their stated TwoRoom audit. Evidence cutoff: 2026-08-20, Asia/Tokyo.
Allowed claim: the four tasks share a broad pipeline but have different pressures, provenance, and source-qualified settings; documented paper/code discrepancies exist. Complete-suite independent reproduction, universal hyperparameters, and score transfer are not established.
Quick check
- Why must paper, frozen-code, and resolved-run history stay in separate boxes?
- In the cited frozen timing, how do five environment ticks, horizon five, and executed prefix five relate?
- What must be locked before two identical success rates become comparable?