Course progress Course outline 48 of 48 lessons available
Part 0 — Reading Guide: What Exactly Are We Going to Learn?
Part 1 — World Models: An Internal Sandbox for the Agent
Part 2 — Turning Images into State: The LeWM Architecture
- 06 Chapter 5 — Trajectory Data: To the Model, the World Is Not an Image Collection available now
- 07 Chapter 6 — The Visual Encoder: Issuing a “State Passport” for Every Frame available now
- 08 Chapter 7 — The Dynamics Predictor: Moving Time Forward in the Mind available now
- 09 Chapter 8 — A Complete Forward Pass: Follow One Batch from Start to Finish available now
Part 3 — Preventing the Model from Cheating: Prediction Loss and SIGReg
- 10 Chapter 9 — The Most Dangerous Shortcut: Representation Collapse available now
- 11 Chapter 10 — Prediction Loss: How the Model Learns the Next Step available now
- 12 Chapter 11 — The Intuition Behind SIGReg: Letting Representation Space “Breathe” available now
- 13 Chapter 12 — Keep the Mathematics Minimal but Sufficient available now
- 14 Chapter 13 — The Original LeWM’s End-to-End Training Mechanism available now
- 15 Chapter 14 — Train a Model That Does Not Collapse Immediately available now
Part 4 — Putting the Model into Action: Planning in Latent Space
- 16 Chapter 15 — Goal-Conditioned Planning: From “Where Am I?” to “Where Do I Want to Go?” available now
- 17 Chapter 16 — Latent Euclidean Distance: Convenient, but Not Necessarily Reliable available now
- 18 Chapter 17 — CEM: Searching for Actions Through an Elimination Tournament available now
- 19 Chapter 18 — MPC: Do Not Trust the Model for Too Long at Once available now
- 20 Chapter 19 — Long-Horizon Rollouts: How Small Errors Snowball into Major Failures available now
- 21 Chapter 20 — Implement a Minimal LeWM Planner from Scratch available now
Part 5 — Engineering Reproduction: From Paper to Running System
- 22 Chapter 21 — The Official Repository and Experimental Environment available now
- 23 Chapter 22 — First Experiment: A TwoRoom Smoke Test available now
- 24 Chapter 23 — Second Experiment: Reproducing PushT available now
- 25 Chapter 24 — How to Evaluate a World Model Fairly available now
- 26 Chapter 25 — Failure-Diagnosis Manual available now
Part 6 — What Has LeWM Actually Learned?
- 27 Chapter 26 — Linear Probes: Which Physical Variables Are Encoded in the Latent State? available now
- 28 Chapter 27 — Give Latent Space a “Health Check” available now
- 29 Chapter 28 — Violation of Expectation: Is the Model Surprised by “Impossible Events”? available now
- 30 Chapter 29 — How to Discuss “Understanding the World” Rigorously available now
Part 7 — Why “Accurate Prediction” Can Still Produce “Poor Planning”
- 31 Chapter 30 — The Gap Between the Training Objective and the Planning Objective Current lesson
- 32 Chapter 31 — Global Non-Collapse Does Not Guarantee Preservation of Task-Relevant Dynamics available now
- 33 Chapter 32 — When Is an Isotropic Gaussian Prior Too Strong? available now
- 34 Chapter 33 — Long-Horizon Planning: Predict Farther or Plan More Intelligently? available now
- 35 Chapter 34 — From Positional Distance to Task Progress available now
- 36 Chapter 35 — Multi-Task Learning, Real Robots, and Visual Distractions available now
- 37 Chapter 36 — Theoretical Boundaries: When Can the True State Be Identified? available now
Part 8 — From Reproducer to Researcher
Appendices
- 41 Appendix A — The Minimum Necessary Mathematical Toolkit available now
- 42 Appendix B — PyTorch Implementation Quick Reference available now
- 43 Appendix C — Complete Tensor-Shape Table available now
- 44 Appendix D — Experiment Configuration Cards available now
- 45 Appendix E — Paper Timeline and Evidence Levels available now
- 46 Appendix F — Glossary available now
- 47 Appendix G — Reproduction Checklist available now
- 48 Appendix H — Expert-Review Checklist available now
The big picture
- PredictWhat follows this action?
- RankWhich ending should we prefer?
- SearchWhich plans did CEM consider?
- ExecuteWhat happened in the world?
A tiny story
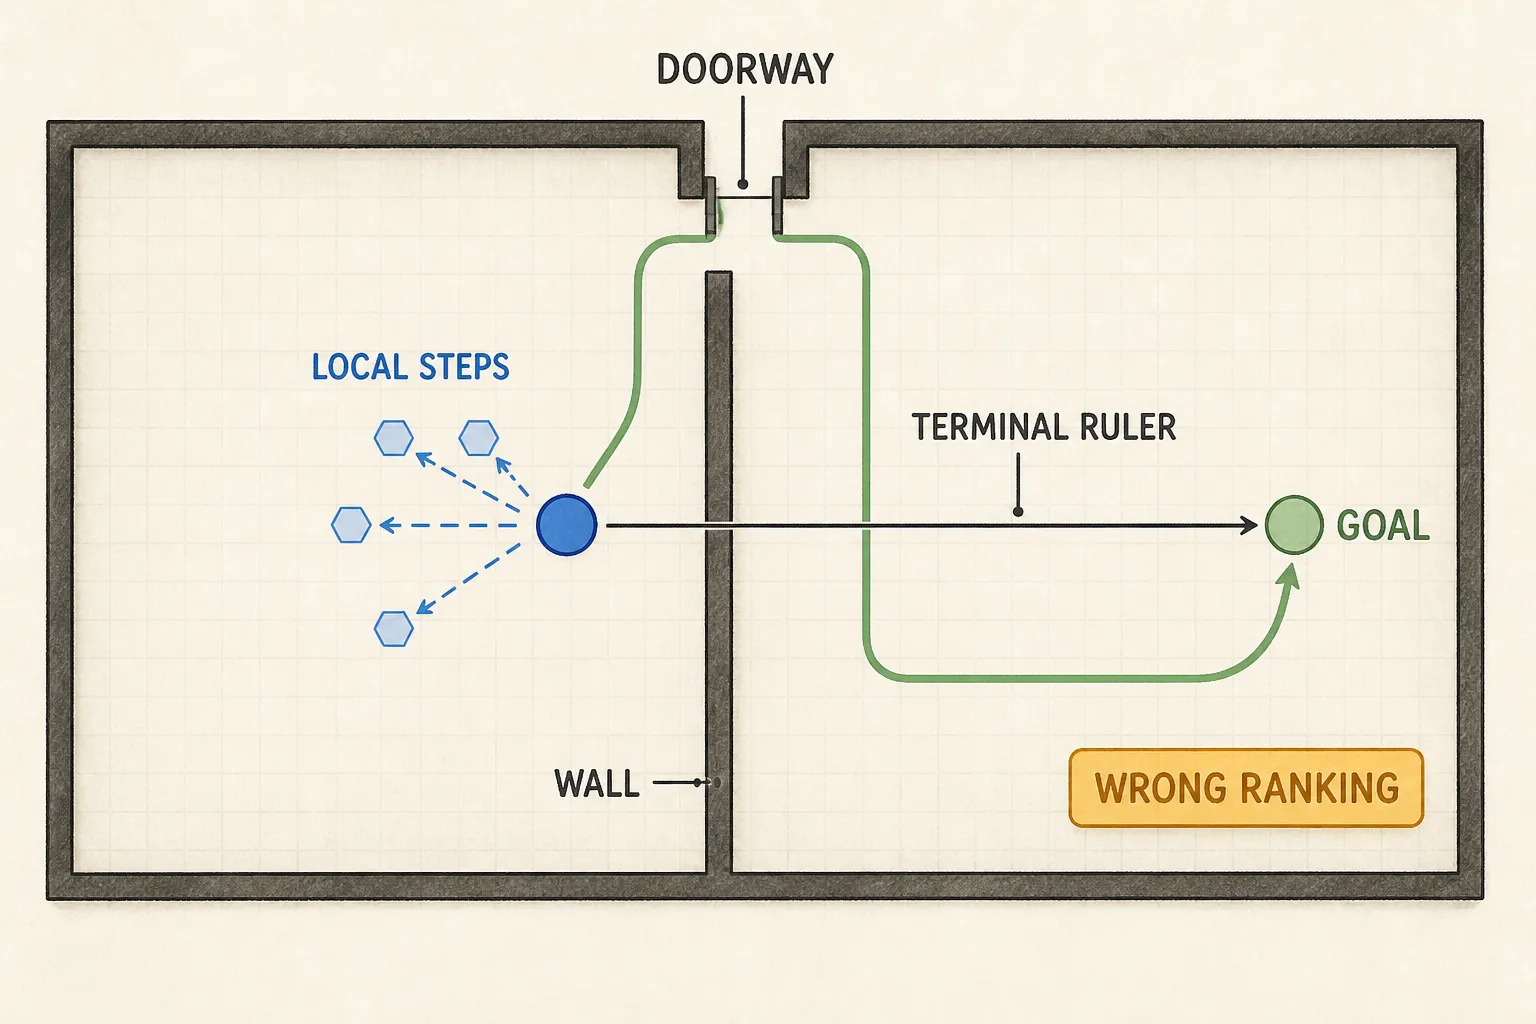
A courier predicts every small step correctly. The goal is close across a wall, so the planner keeps choosing “walk toward the goal.” The courier presses into the wall instead of moving away toward the doorway.
Nothing in this story requires bad next-step prediction. Training asks, “Did this action lead to the correct next latent?” Planning asks, “Which whole sequence should be preferred?” Original LeWM v3 answers the second question with terminal squared latent Euclidean distance. A forecast and a route judgment are not the same object.
The real rule
Low mean squared prediction error cannot guarantee a good ordering because:
- common local motion can dominate rare doorway or contact decisions;
- a representation can predict nearby transitions while arranging wall-separated endpoints badly;
- planning evaluates self-fed, model-generated states, not only recorded contexts;
- Euclidean cost is symmetric and has no explicit direction, budget, support, or uncertainty argument.
Use oracle substitutions before changing the whole model:
oracle rollout + learned cost still ranks badly
  → inspect cost or representation geometry
learned rollout + oracle cost fails
  → inspect multi-step dynamics and support
both oracles succeed, deployed planner fails
  → inspect search, observation, action conversion, execution
An oracle is a laboratory instrument with privileged simulator access, not a deployable pixels-only component.
Two later proposals change different jobs. RC-aux replaces the original one-step prediction term with weighted multi-horizon open-loop prediction whose horizon set still includes step 1, and adds a budget-conditioned reachability head. Temporal-Distance JEPA learns a separate directed temporal cost and an (H=5) rollout-consistency loss matching each predicted latent to a stop-gradient encoding of the recorded future. That local detach belongs to the later method; original v3 targets remain connected.
Trajectory offsets are evidence of what one behavior did, not oracle shortest times. Cross-trajectory negatives can also be false.
The trick that can fool us
First change only the ruler. Use exact simulator endpoints for a fixed TwoRoom candidate bank. Rank them by straight-line distance and by wall-respecting graph distance. Remove the wall and repeat.
If graph distance changes the ranking only when the wall creates a detour, the topological-cost explanation survives this toy removal test. If both costs fail with exact endpoints, inspect candidate coverage or task definition. Then add learned encodings, reverse direction, vary the budget, and only afterward add learned rollout.
Do not call every later method the same “planning-aware objective”:
- Objective Bottleneck freezes one TwoRoom representation/predictor and swaps planner cost.
- Traj-LeWM adds a goal-conditioned latent trajectory cost, synthetic ranking negatives, and after each epoch mines failed endpoint-only executions to train that cost.
- Decision-Metric Alignment measures Plan–Real and CEM-stage Spearman, then adds training-only inverse-dynamics and goal-action heads while retaining Euclidean MPC cost.
These interventions target ruler, path, and representation geometry respectively.
Experiment receipt
The Objective Bottleneck follow-up reports latent L2 versus true distance at (r=0.426) despite a position ridge probe at (R^2=0.9922). On its checkpoint, an offset-100 temporal cost changes success from 26% to 98%; on the released checkpoint it changes 14% to 34%, while privileged decoded-position cost reaches 70%. This is one environment, one seed per checkpoint, and a non-v3-default long-goal protocol.
Traj-LeWM reports gains of 3, 14, 7, and 7 percentage points on PushT, Cube, Reacher, and TwoRoom over its LeWM comparison, averaged over three evaluation seeds. Its failure mining means the intervention is not purely offline-data training.
Decision-Metric Alignment reports one training run per configuration; its three seeds quantify evaluation variation, and its rank diagnostics require simulator rollout. These are author-reported results, not independent reproduction.
The baseline source remains LeWorldModel v3, commit 8edfeb3. No later stop-gradient, reachability, temporal, or action-head objective may be drawn backward into v3.
Quick check
- How can oracle dynamics still produce bad TwoRoom planning?
- What different jobs do multi-horizon prediction and reachability scoring perform?
- Which oracle cell tells you to change the ruler before the predictor?